The Technology Stack
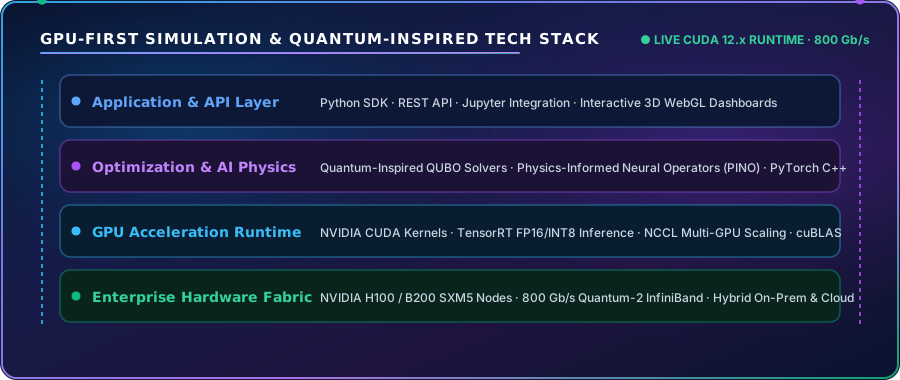
We believe engineering software should be written for modern GPU clusters from line one, not ported decades later as an afterthought.
NVIDIA CUDA & TensorRT
Our core physics solvers and neural operators are written as native CUDA C++ kernels, optimized for FP16 and INT8 tensor core execution on NVIDIA H100 and B200 hardware.
Physics-Informed Neural Operators (PINO)
We train Fourier neural operators that approximate PDEs across continuous domains, providing full 3D velocity and pressure tensor fields without tedious re-meshing.
Quantum-Inspired QUBO Optimization
Combinatorial optimization formulated as Quadratic Unconstrained Binary Optimization (QUBO), solved with GPU-simulated quantum annealing to conquer rugged Pareto frontiers.
Slurm & Kubernetes Elastic Orchestration
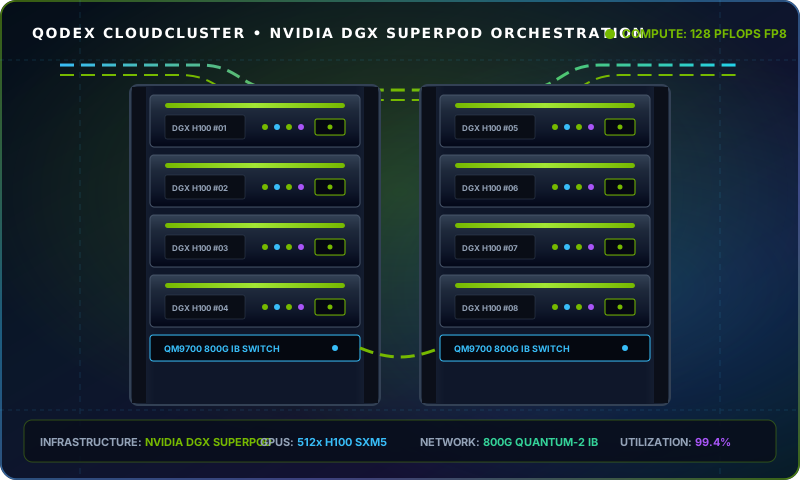
Our distributed cluster scheduler distributes thousands of simultaneous surrogate evaluations across multi-node InfiniBand networks with zero idle GPU cycles.
Massive Parallelism Across H100 GPU Clusters
Traditional simulation queues stall because high-fidelity solvers consume tens of node-hours per shape. By decoupling parameter exploration from solver latency, our cluster orchestrator sweeps 10,000 configurations with 99.4% GPU compute utilization.
Scales seamlessly from a single desktop workstation with an RTX 4090 to 512-GPU cloud clusters connected over 800 Gb/s InfiniBand.
Read the benchmarks or test the SDK
Contact our engineering team to review detailed convergence benchmarks or run an evaluation notebook.
Get in Touch